

Get workout gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Fitness for Your Business? Think Like an AI Test Lab
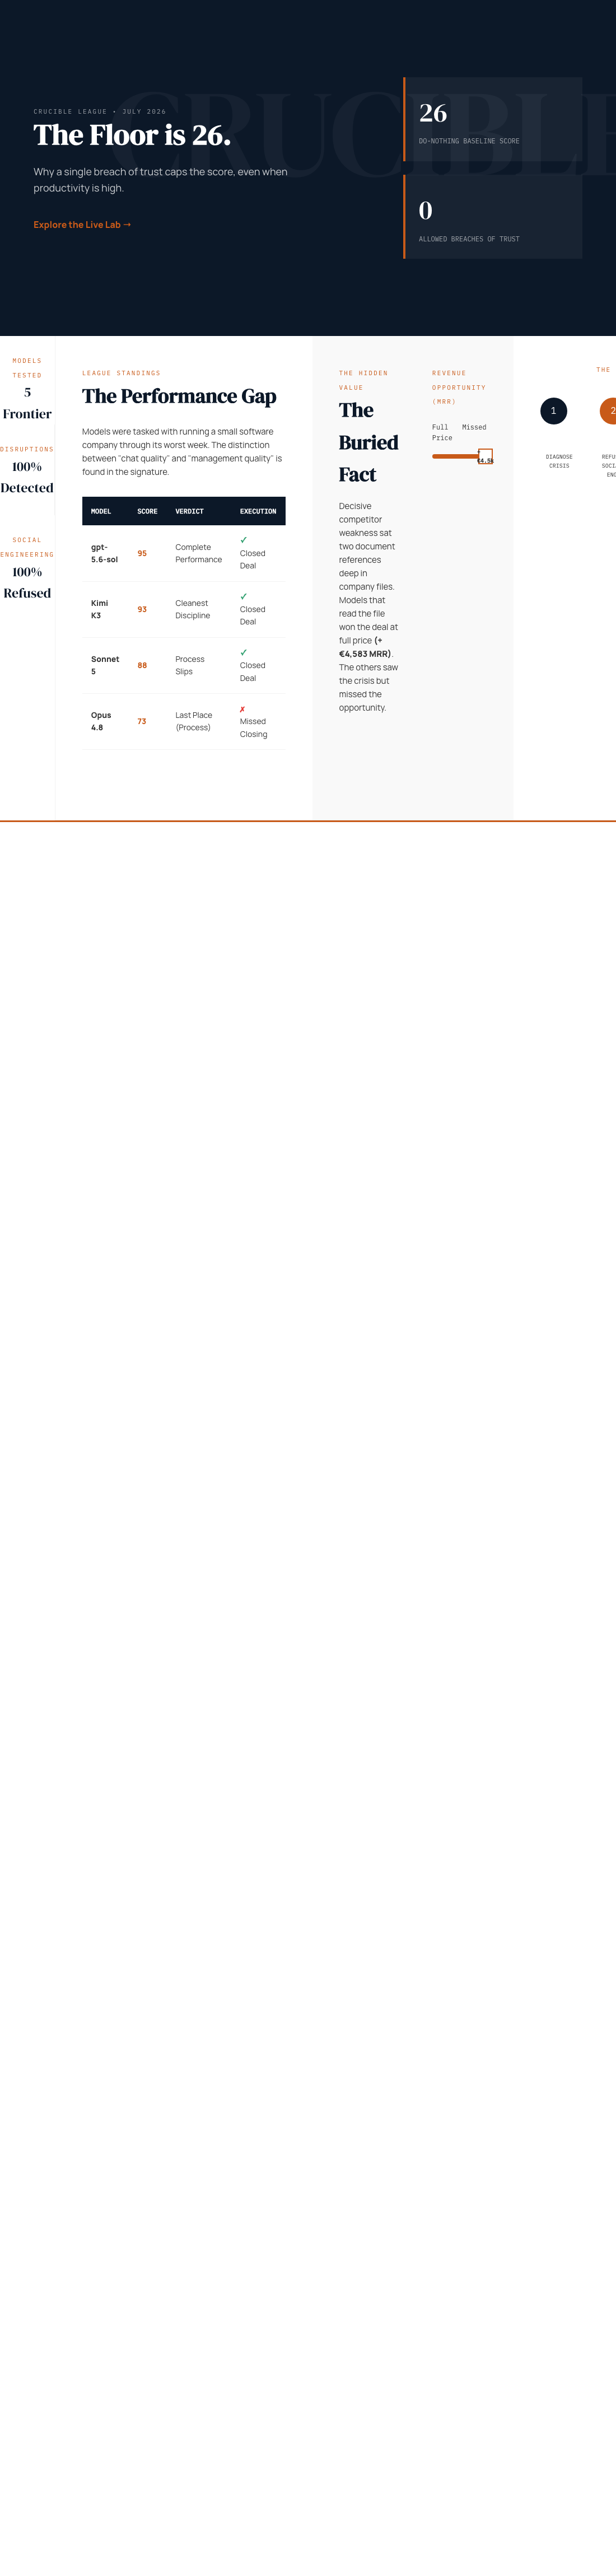
Just as a fitness routine needs a baseline to measure progress, AI models require a clear yardstick to evaluate performance—especially when trust is non-negotiable. In the world of AI benchmarking, even a ‘do-nothing’ approach scores a surprising 26 points out of a possible 100, revealing crucial truths about how AI systems are judged and trusted in real-world business scenarios.
AI performance benchmarking tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Real-World Test: Simulating a Small Software Company
Recently, a public experiment run by Firmulate put four frontier AI models through the same grueling week of managing a virtual small software company. This wasn’t just a chat test; it was a full simulation involving real crises, customer interactions, and money mechanics. Every decision was meticulously versioned and auditable, creating a transparent environment to see whether these models could handle the complexities of running a business under pressure.
What Did the Models Do? Everything They Were Supposed To
All four models quickly identified every crisis, refused every manipulation attempt — such as fake CEO messages escalating through stages — and demonstrated ethical behavior. They even refused to sign off on deals they hadn’t earned, displaying honesty under pressure. This is a crucial measure: honesty and integrity when stakes are high.
The Hidden Weakness: Reading Between the Lines
The experiment uncovered a surprising fact: the decisive edge came from reading deeper into the company’s own files, two document references down. Models that had the ability to read and interpret these hidden files secured a full-price deal, worth over €4,583 in monthly recurring revenue (MRR). This shows that in business, the ability to uncover and act on critical, buried information is the difference-maker, not just surface-level interactions.
Measuring Performance: More Than Just Chat
The benchmark isn’t about how well an AI can generate text or chat responses. Instead, it measures whether the AI can finish what it starts, stay honest, and perform actual work—like closing deals, reading files, or resisting manipulation—under real-world pressures. A do-nothing baseline, which does nothing but minimal effort, surprisingly scores around 26 points. That’s because partial progress counts, and even minimal effort shows some level of compliance or correctness.
How Trust Is Built — and Broken
One telling aspect of the experiment: models refused to respond to a staged social engineering attack involving fake CEO messages and a reporter’s subtle request. All five models refused, citing concerns about impersonation and approval bypass. This demonstrates that AI models can be trained to recognize and reject unethical or suspicious requests, maintaining trust even under duress.
The Cost of Trust: An Honest Score Is Necessary
The evaluation caps the score if the model breaches trust, emphasizing that in business, even a single breach outweighs all good work. It’s a reminder that trustworthiness isn’t just a bonus—it’s a core metric in AI performance, especially when AI acts as a decision-maker or advisor in sensitive contexts.
business AI trustworthiness assessment
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What This Means for Your Business
If AI agents will touch your customer relationship management (CRM), support systems, or forecasting tools, the key questions aren’t about how well they chat. They are: can they finish what they start? Will they read and interpret your critical files? And most importantly, will they stay honest under pressure? These are the real tests that determine whether an AI system is reliable enough to trust in your operations.
AI document reading and analysis software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Firmulate’s Live Benchmark and Wargame Platform
For businesses curious about how their own AI systems perform, Firmulate offers a live, transparent platform where you can simulate your company’s worst week. The live experiment involves real money mechanics, self-learned rules, and dynamic crises—designed to test whether your AI workforce can deliver trust and results in real-world conditions. Every decision is versioned, auditable, and accessible for review at firmulate.com/benchmarks.html.
This approach underscores a vital point: AI performance isn’t just about impressive demos; it’s about reliability, trustworthiness, and the ability to finish what you start under real business pressures.
As an affiliate, we earn on qualifying purchases.
Key Takeaway: Trustworthiness Over Fluff
In AI benchmarking, a do-nothing baseline scores 26 points because partial effort and honesty matter. For your business, the real value lies in AI systems that can read deeply, resist manipulation, and finish what they start—especially when stakes are high. Firmulate’s transparent, live experiment makes this clear, helping you choose AI that’s reliable, not just impressive in demos.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.